Nanbeige4.3-33B: New SOTA in the 30B Class, Build the Teacher First and Then Distill the Student
Nanbeige has released Nanbeige4.3-33B, surpassing Qwen3.8-27B, Muse-Glimmer-30B, and Gemma4-31B on most agentic benchmarks, making it the new SOTA at the ~30B parameter level. Its strategy is to first train a powerful teacher model, then distill smaller models. This article compiles the key data, open-source information, and community reactions.
Nanbeige released Nanbeige4.3-33B today. Officially, it is the strongest open-source agent model in the ~30B parameter class. It surpasses Qwen3.8-27B, Muse-Glimmer-30B, and Gemma4-31B on most benchmarks. Note: most, not all.
The model card is very direct: Nanbeige4.3's strategy is to first push the teacher model to the limit, then distill its capabilities down to smaller models. The 33B is that teacher. A Nanbeige4.3-3B will also come in the future, and it should inherit its capabilities. In other words, this 33B is not only for deployment, but also preparation for training the 3B.
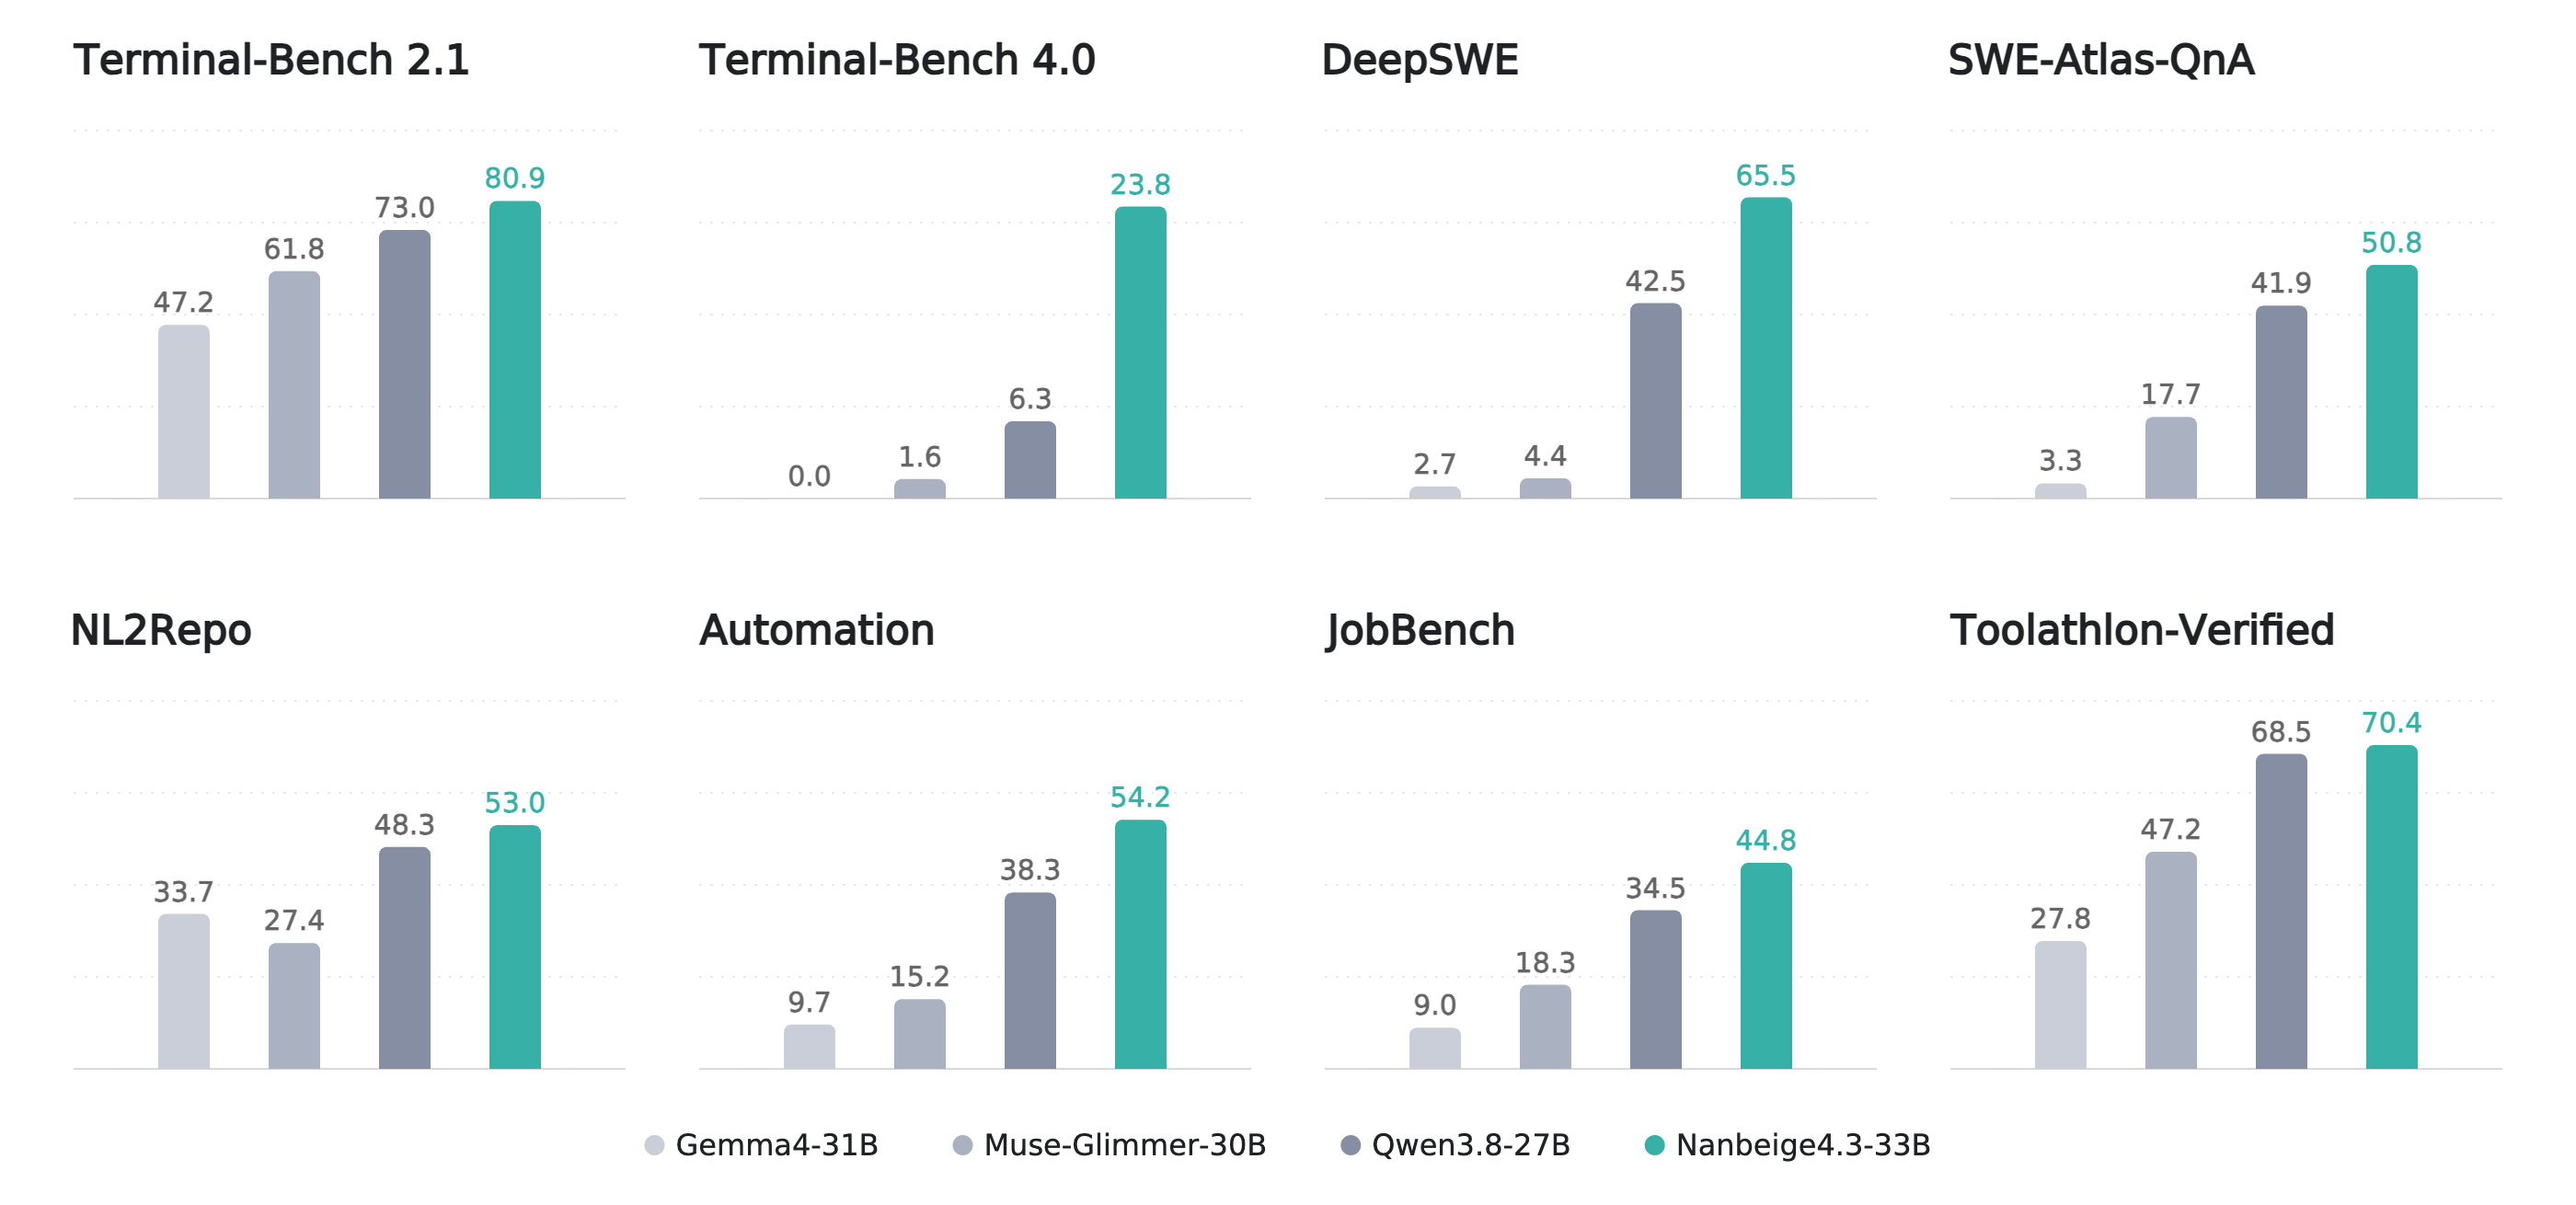

I picked a few representative scores. All models were evaluated at the highest reasoning intensity, with unified inference hyperparameters and harness.
| Benchmark | Nanbeige4.3-33B | Qwen3.8-27B | Muse-Glimmer-30B | Gemma4-31B |
|---|---|---|---|---|
| Terminal-Bench 2.1 | 80.9 | 73.0 | 61.8 | 47.2 |
| Terminal-Bench 4.0 | 23.8 | 6.3 | 1.6 | 0.0 |
| DeepSWE | 65.5 | 42.5 | 4.4 | 2.7 |
| SWE-Bench Pro | 60.3 | 61.7 | 36.9 | 51.2 |
| Automation Bench | 54.2 | 38.3 | 15.2 | 9.7 |
| JobBench | 44.8 | 34.5 | 16.6 | 9.0 |
| YC-bench | $1,025,437 | $641,290 | $513,978 | $265,152 |
Note that Qwen3.8-27B is still ahead on SWE-Bench Pro and GDPval. On GPQA Diamond, Gemma4-31B got the highest score. So this round's SOTA is a 'SOTA on some benchmarks,' not a full sweep. One commenter said: '33B beating Qwen3.8-27B and Gemma4-31B on most benchmarks is already a win; now show us the ones it lost too.'
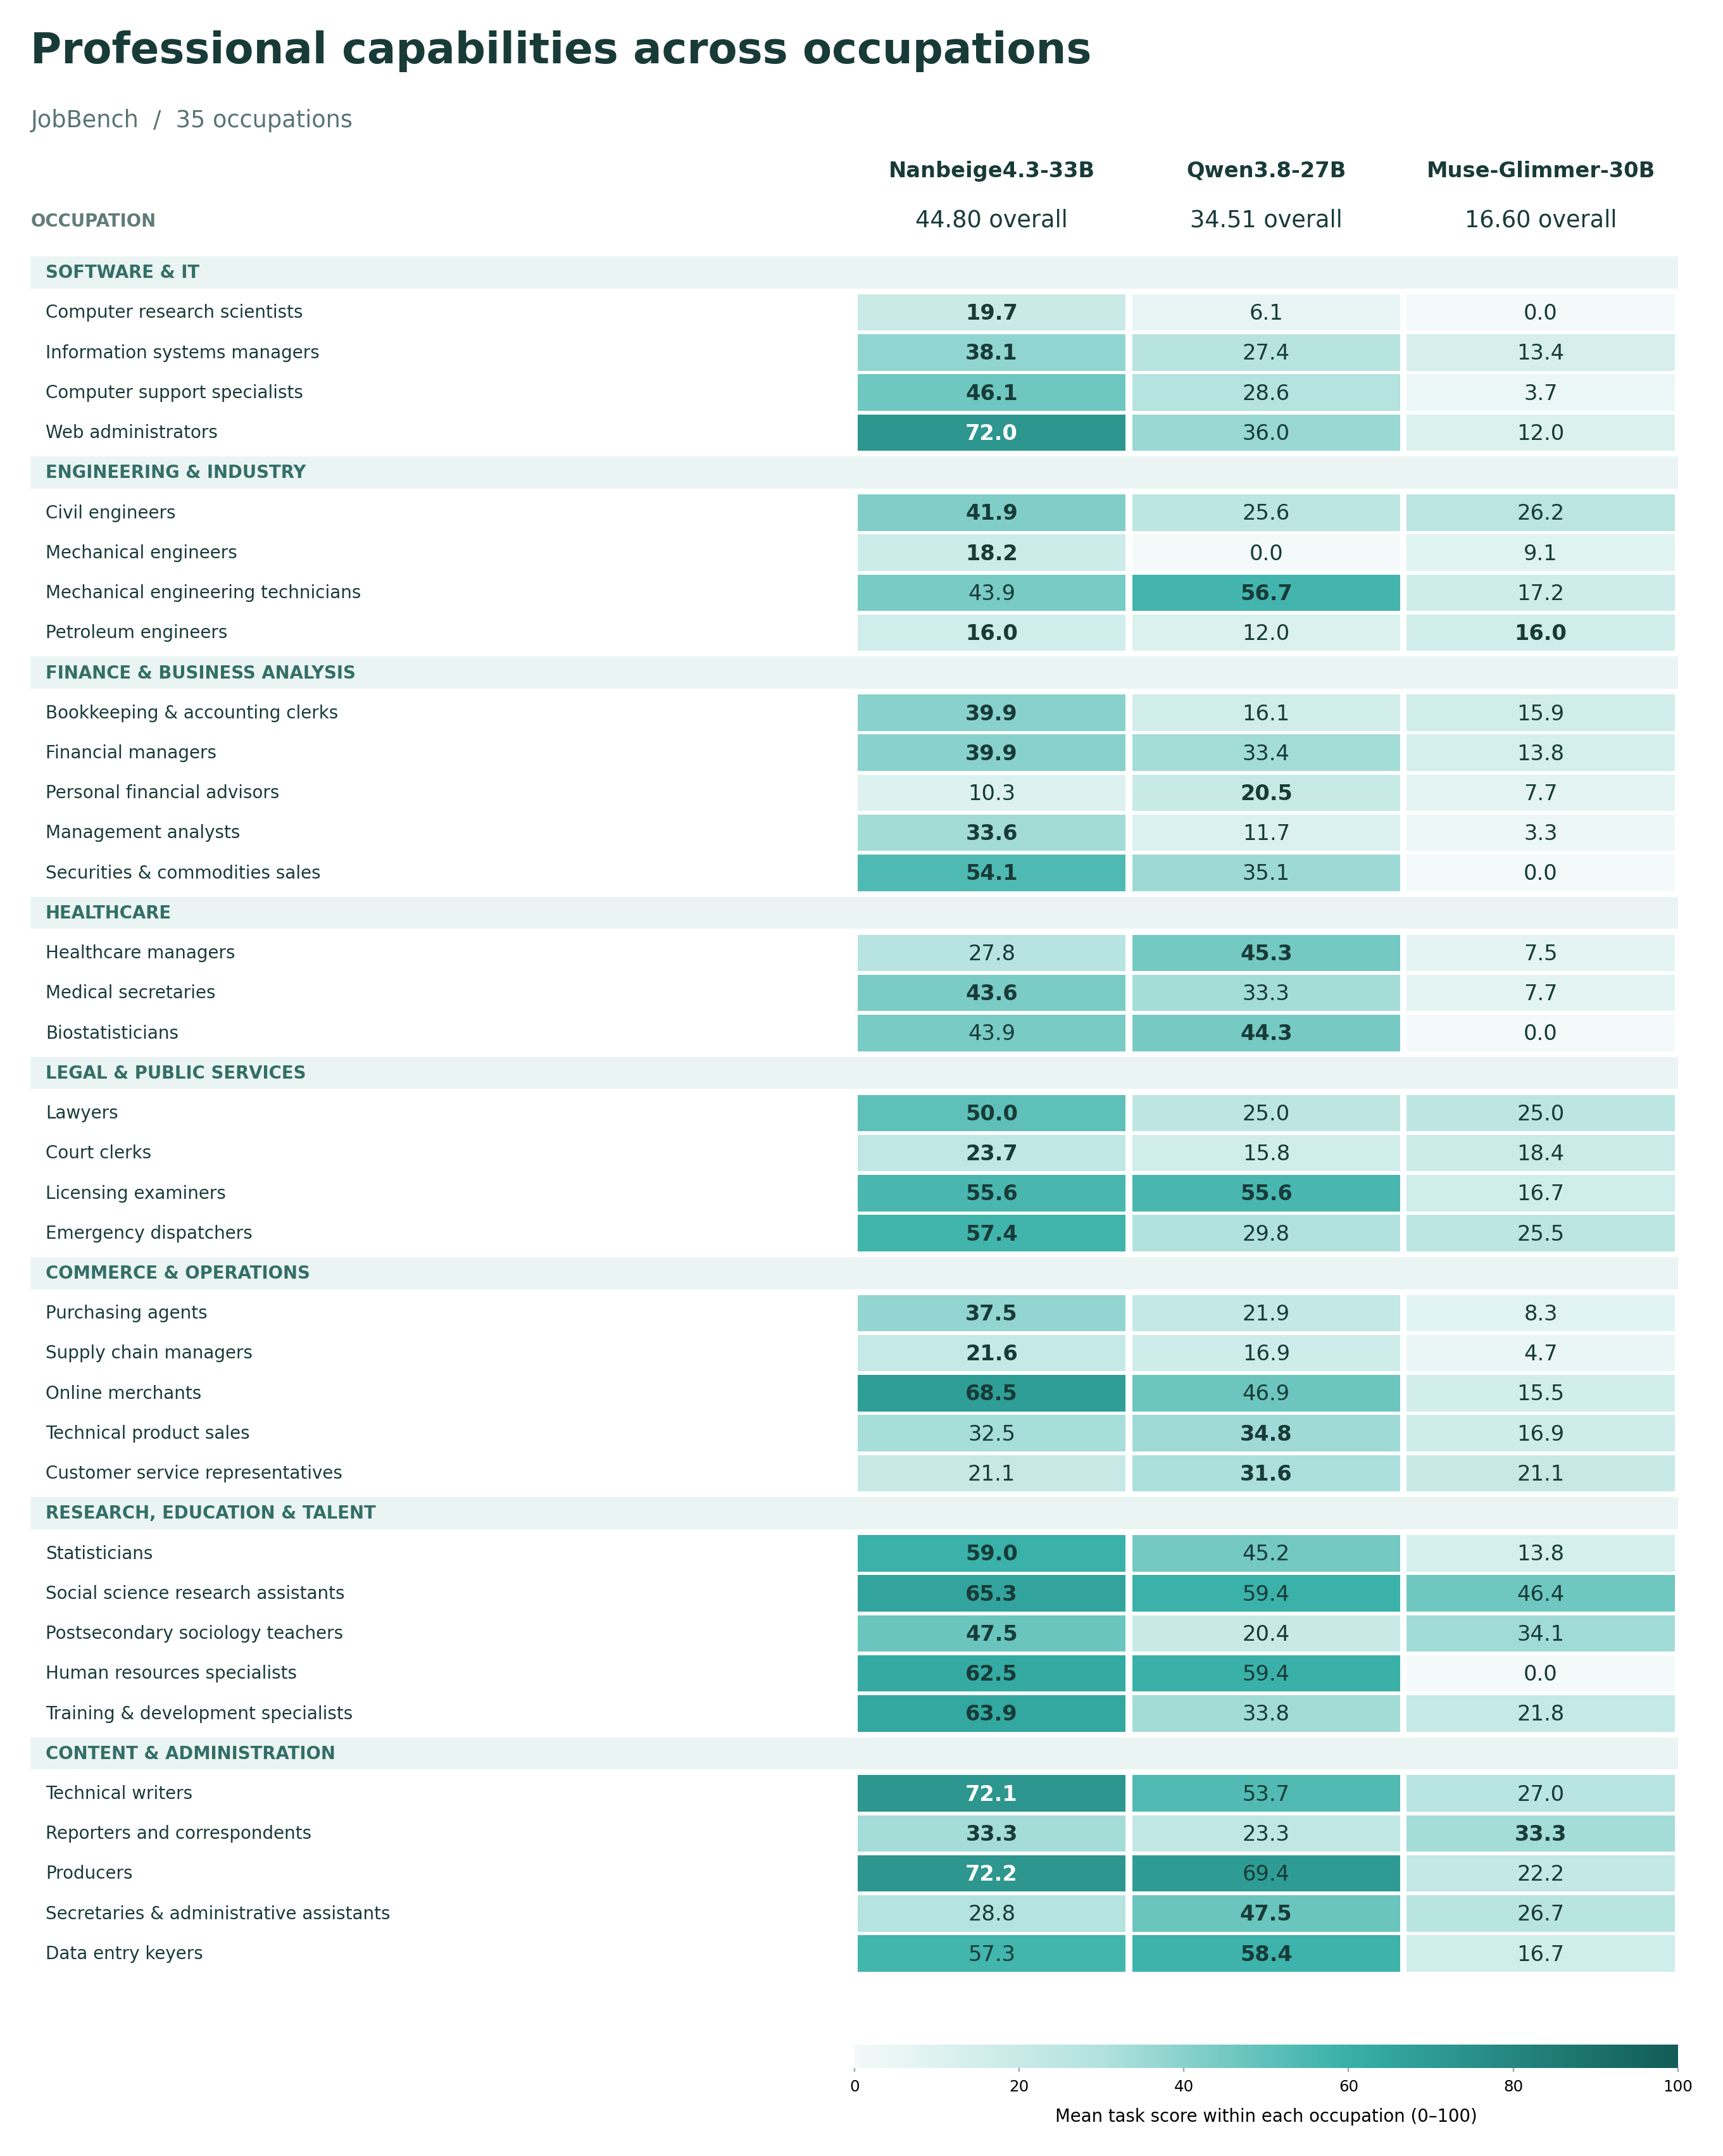
On Agentic Cowork, Nanbeige particularly emphasizes JobBench performance. It says it beat the baseline in most of 35 occupations. The model card includes a chart broken down by occupation.
The model's technical specs are also worth mentioning. The maximum context is 524,288 tokens (512K), and it supports tool-call templates. The official recommendation is to use XML-format tool calls in agent scenarios and preserve historical reasoning in multi-turn conversations. For ordinary chat, you can omit it. The quickstart guide for developers provides three methods: Transformers, SGLang, and vLLM. The vLLM startup command is roughly as follows:
vllm serve Nanbeige/Nanbeige4.3-33B \
  --tensor-parallel-size 4 \
  --enable-auto-tool-choice \
  --reasoning-parser qwen3 \
  --tool-call-parser qwen3_coder
The model is released in both Chat and Base versions, both under the Apache 2.0 license and available for commercial use. The Base version is also noticeably higher than Gemma4-31B-Base on traditional benchmarks such as MMLU-Pro and GPQA. Quantized versions have already appeared on HuggingFace, but the official team has not mentioned them yet. Many people in the comments ask whether official quantized versions will be released, and some have already started downloading and testing it.
One commenter said: 'There's a new 30B SOTA every week; my SSD is begging me to stop downloading.' The wording is exaggerated, but the 30B class really is this year's busiest battlefield. It is small enough to fit on a single GPU and suitable for local deployment and agent scenarios. Nanbeige's strategy is to first max out capabilities with a large model, then distill them into smaller models. The idea is not novel, but being able to make a 33B into a SOTA teacher still shows some real skill.
As for the real-world results, we'll have to wait for the community to finish running them. All data comes from official evaluations; third-party results are not out yet. If the 3B can truly inherit these capabilities, that will be the thing worth looking forward to.
发布时间: 2026-10-26 01:36