BOSS Zhipin Releases Nanbeige4.3-33B: Leading Across Agent Benchmarks—What Is the Community Questioning?
The 33B Dense model surpasses Qwen3.8-27B on multiple Agent benchmarks, with 512K context and Apache 2.0 open source. It is officially positioned as a teacher model, with a 3B distillation planned next. Quantizations already exist and it can run on a single GPU, but there are also plenty of concerns about its architecture and inference overhead.
BOSS Zhipin's Nanbeige team has released Nanbeige4.3-33B. It has 33B parameters, a dense architecture, 512K context, and an Apache 2.0 license. The team has released both Chat and Base weights on Hugging Face and directly compared it with Qwen3.8-27B, Muse-Glimmer-30B, and Gemma4-31B.
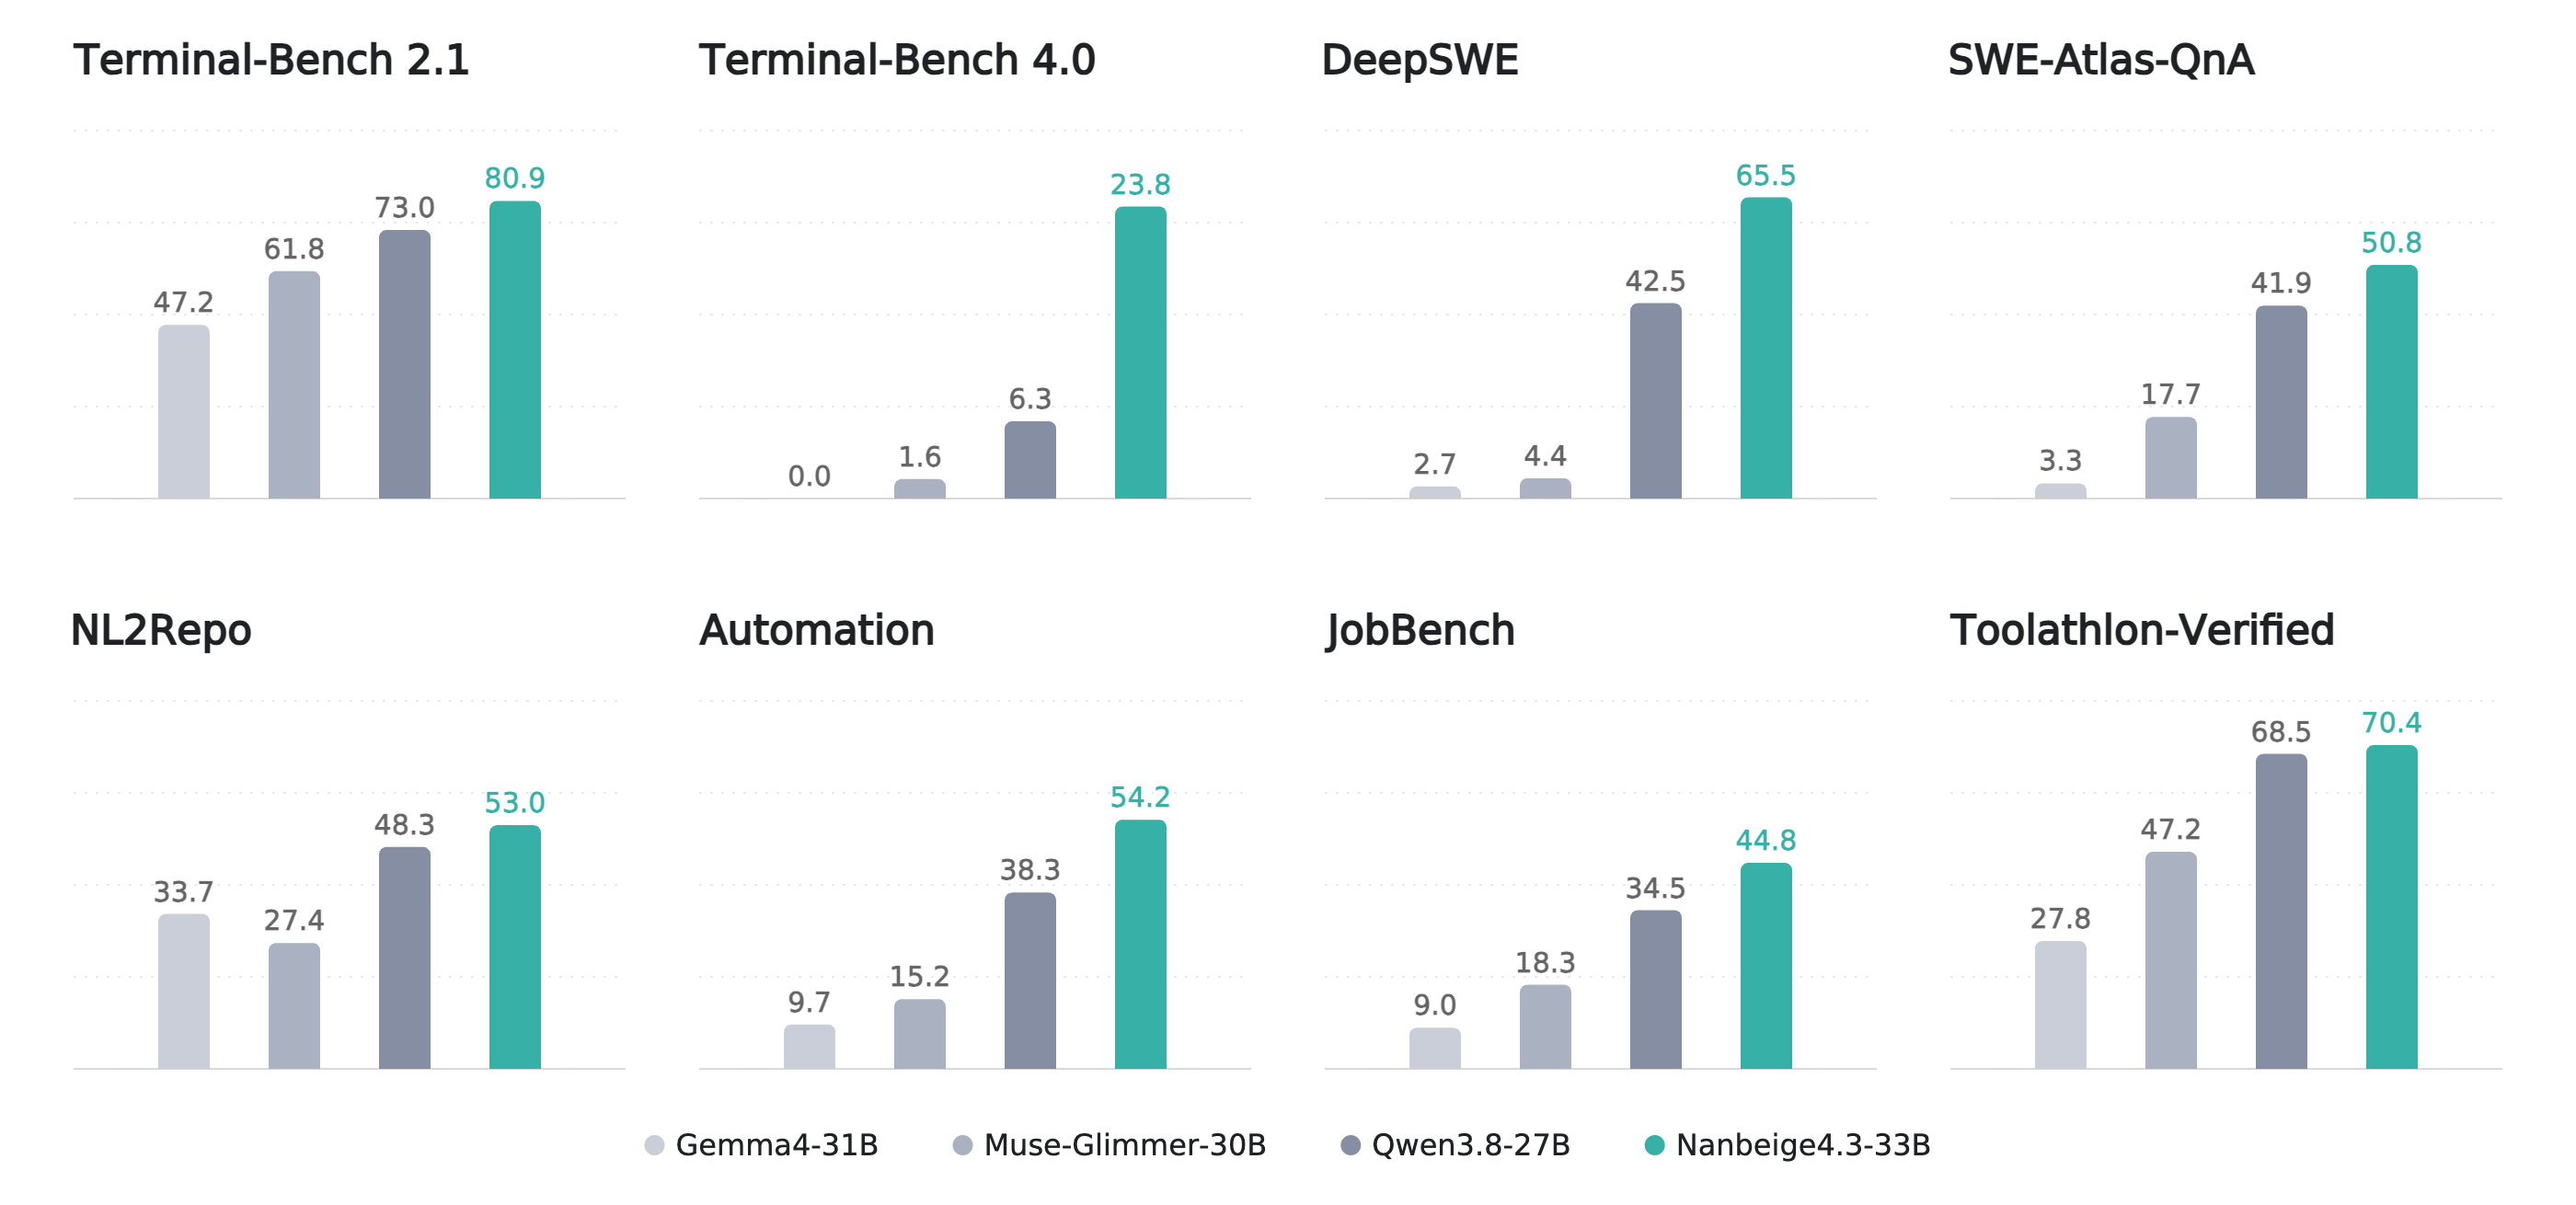
On Terminal-Bench 2.1, Nanbeige4.3-33B scores 80.9, while Qwen3.8-27B scores 73.0. On DeepSWE it is 65.5 vs. 42.5, on Automation Bench 54.2 vs. 38.3, and on DeepPlanning 63.3 vs. 49.2. It leads on most Agent benchmarks, especially tasks such as terminal operation and software engineering, where the gap is relatively large.
This model has a clear identity: teacher. The Nanbeige4.3 series first builds a large model, then distills Agent capabilities into smaller models; the team explicitly named the upcoming Nanbeige4.3-3B. In other words, 33B is transitional, and 3B is the terminal product intended for scale. It also makes sense for a recruiting platform to build agents: resume screening, job matching, and interview scheduling are all tasks that require multi-step tool calls.


The community moved quickly. Someone has already produced a GSQ-RCO GGUF quantization, and a single 4090 with 48GB of VRAM has a chance to run it. Fifty quantized versions are already listed on Hugging Face. But skepticism has also appeared at the same time. Some netizens say the scores are too impressive and they need to pull it down and run it themselves before believing it. Some point out that the architecture is still the old Llama stack, with full attention and no linear layers, so inference cost and KV overhead are both high, and it cannot run locally with long contexts. Others are waiting for the 3B distilled version and think 33B is not the final answer.
The model card contains a detailed Benchmark table, and the team also notes the harness used for each benchmark—for example, NL2Repo uses Claude Code, and JobBench also connects to the Claude Code harness. This means the scores cannot simply be compared horizontally, because the evaluation environments for different tasks are not consistent. How good the actual Agent capabilities are still has to be seen by deploying it.
A recruiting platform open-sourcing a 33B Agent foundation model is itself somewhat counterintuitive. But on closer thought, Agent models are more tightly bound to data and scenarios, and BOSS Zhipin happens to have a large amount of real workplace task data. The next step is to see how much Agent capability the 3B distilled version can retain; that is the key to whether this series has any relevance.
The pressure is now on Qwen4. The open-source community has gained another runnable Agent foundation model, and it is accessible on a single GPU. Whether Nanbeige4.3-33B actually works will be decided by the people who have run it.
发布时间: 2026-10-26 12:50