Recruiting software released a 33B open-source model; its Terminal-Bench score beats Qwen 27B—but don't rush to switch
BOSS Zhipin's research team Nanbeige released Nanbeige4.3-33B. It beats Qwen3.8-27B on several Agent benchmarks but still lags on SWE-Bench Pro and GDPval. With 512K context, only about 10K remains on a 24GB GPU; netizens are waiting for third-party reruns.
A research team from a recruiting software company just released a 33B open-source model.
Nanbeige, under BOSS Zhipin, released Nanbeige4.3-33B, with weights on Hugging Face under Apache 2.0. Thom Wolf gave a memorable analogy on X: BOSS Zhipin is like WhatsApp plus LinkedIn. Now a model team has grown out of that combination, and what it delivered beats Qwen3.8-27B on several Agent benchmarks.
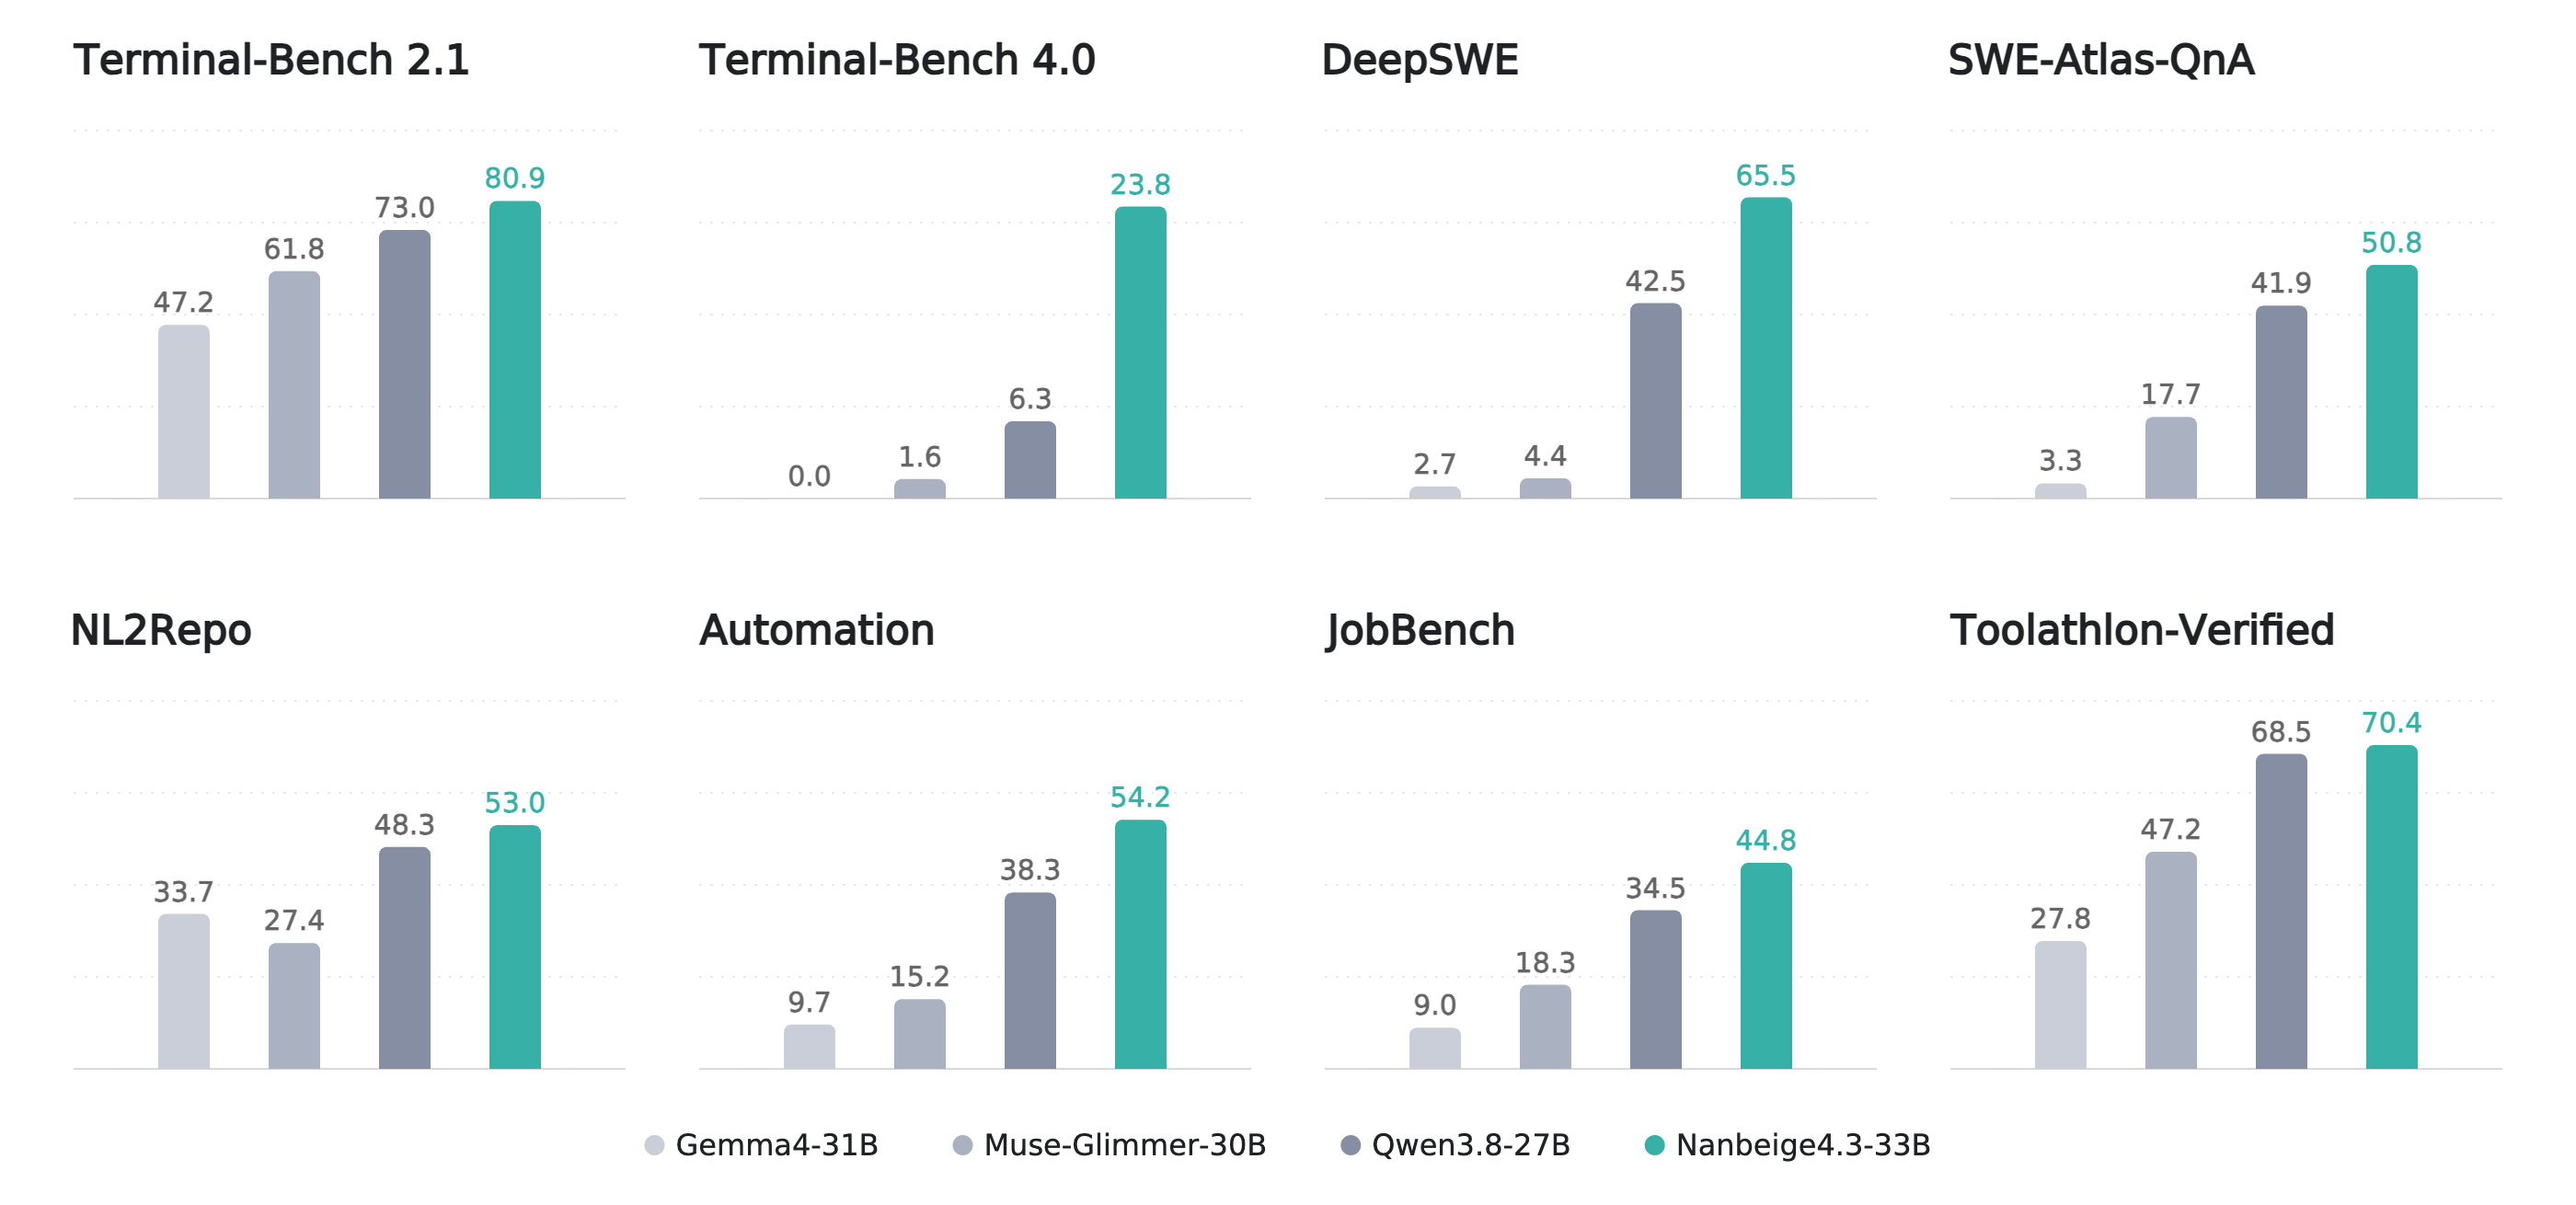
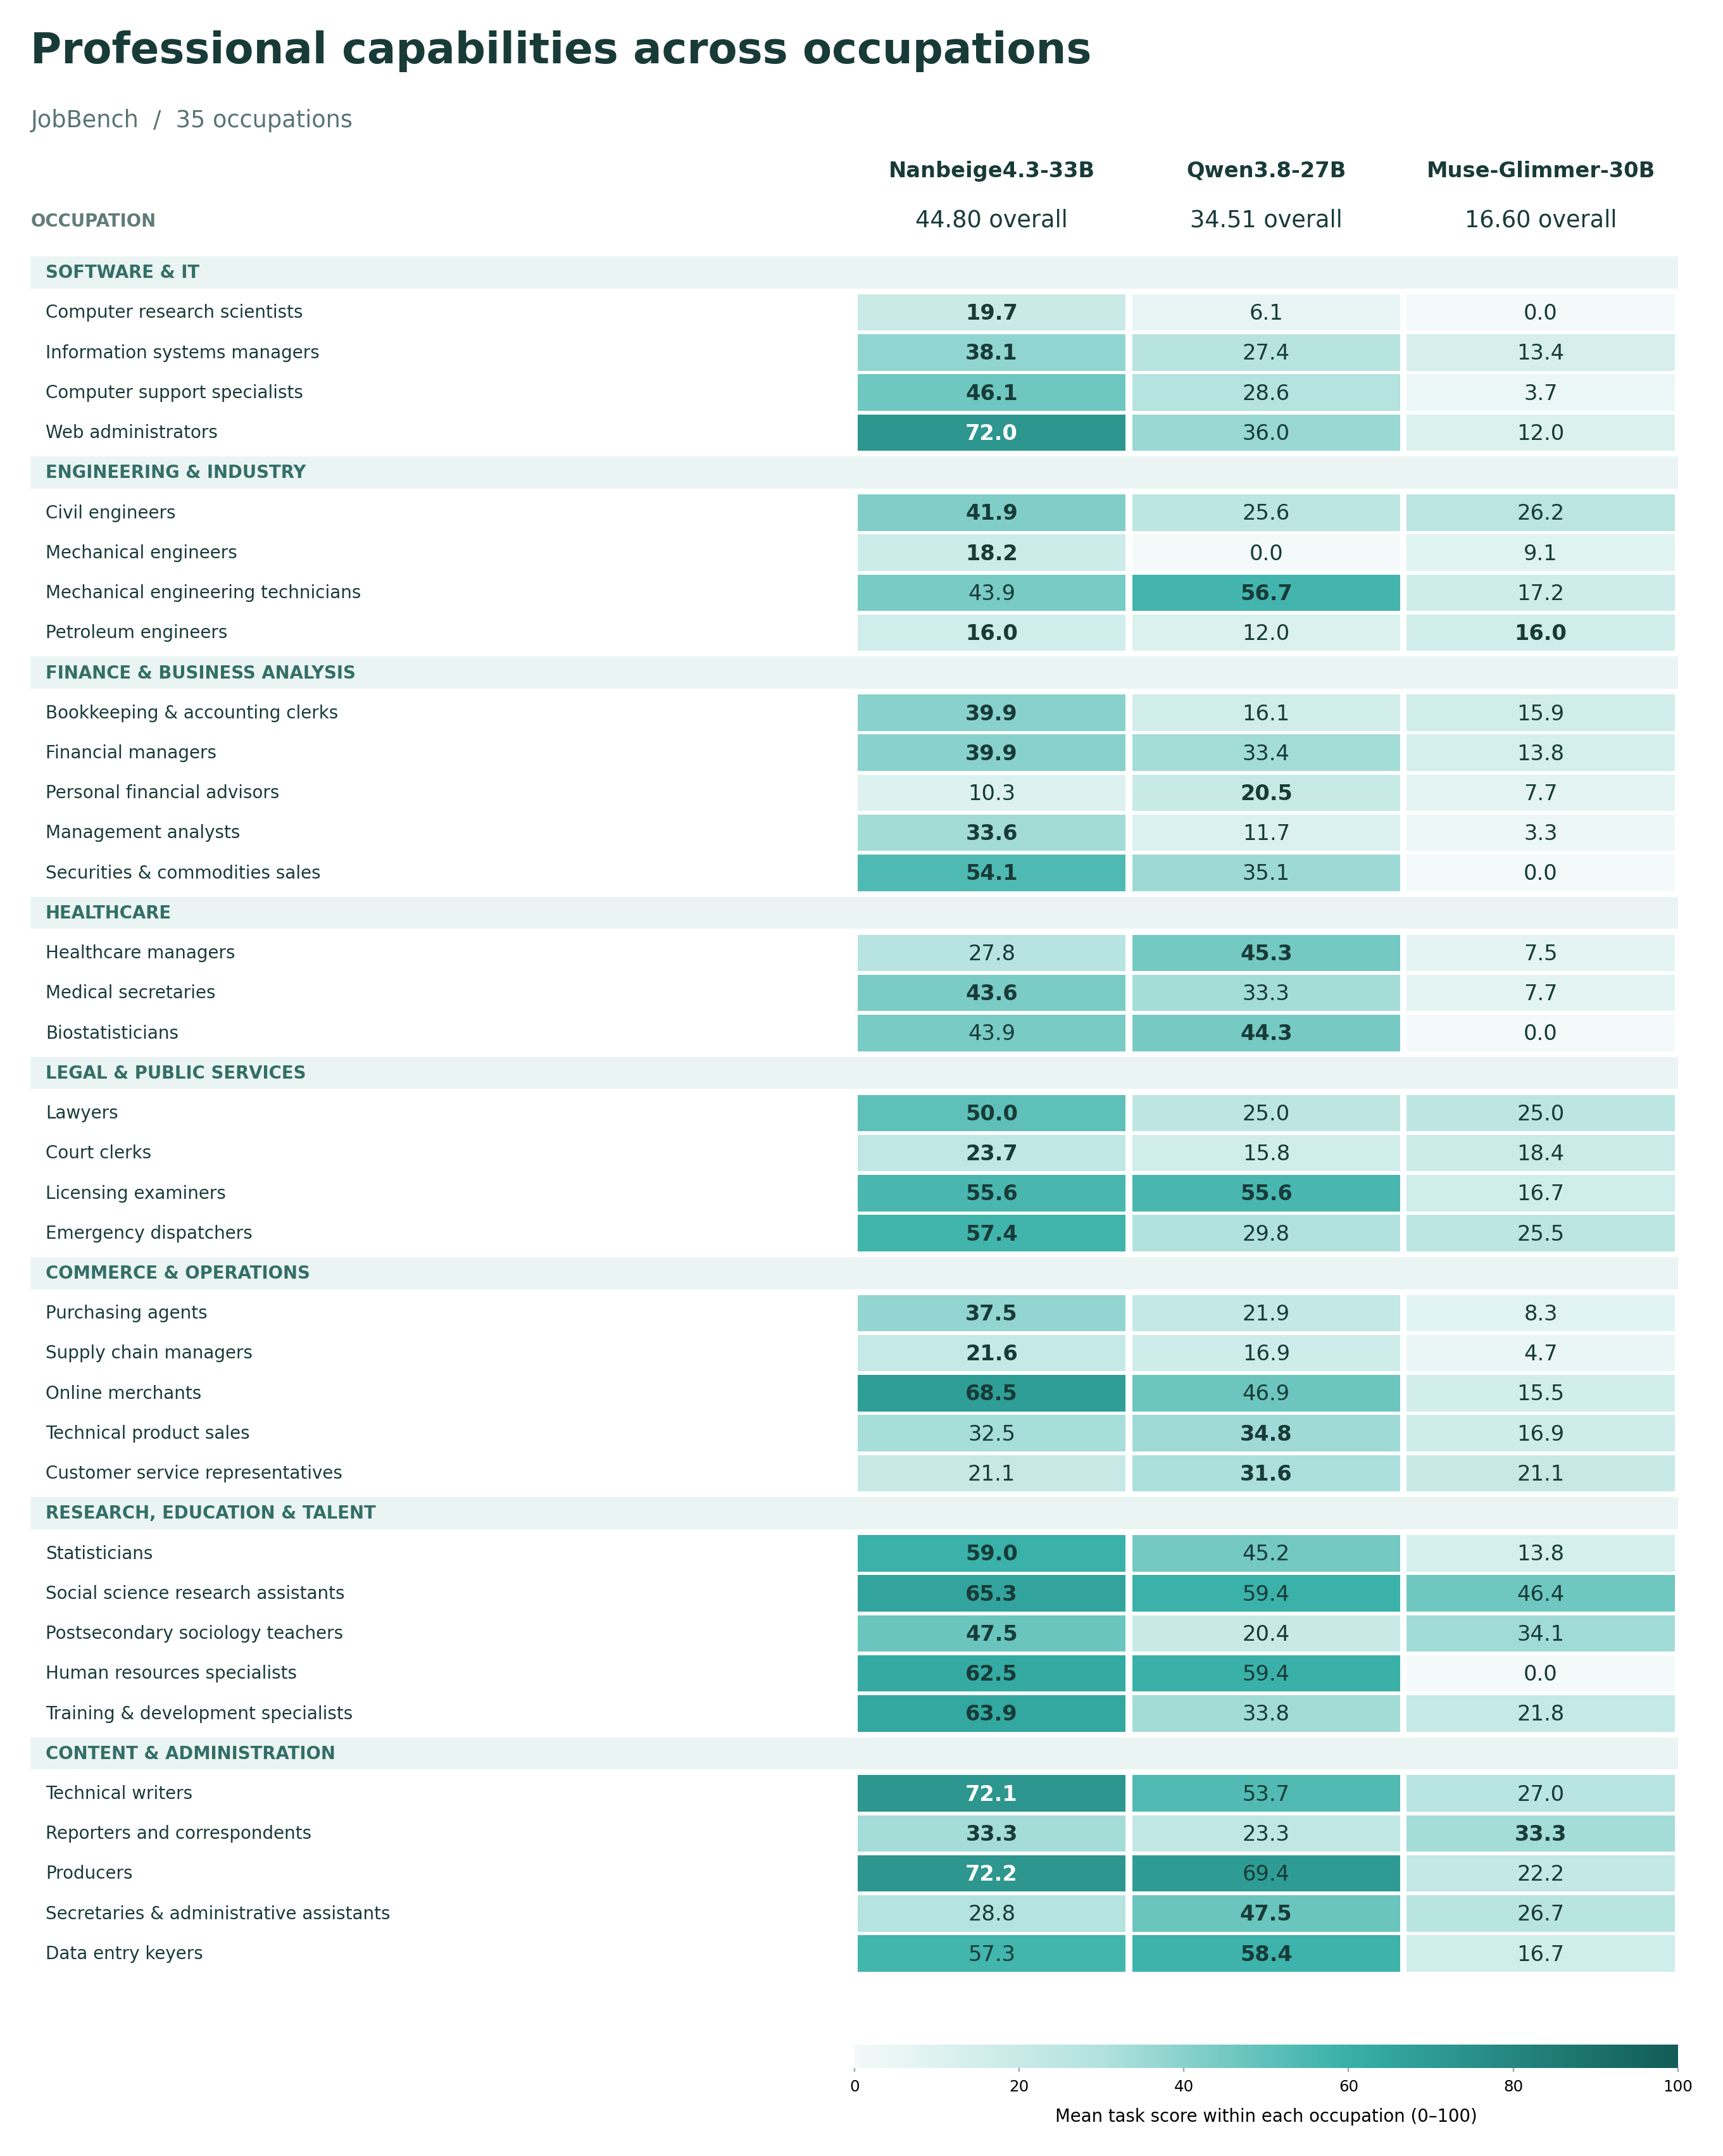
First, the scores. On Terminal-Bench 2.1, Nanbeige4.3-33B scores 80.9, while Qwen3.8-27B scores 73.0. On Terminal-Bench 4.0, it's 23.8 vs. 6.3. DeepSWE: 65.5 vs. 42.5. Automation Bench: 54.2 vs. 38.3. JobBench: 44.8 vs. 34.5. YC-bench reports $1,025,437, versus $641,290 for Qwen.

But the table was run by the lab itself. Nanbeige used preserve_thinking=true here, while Qwen still leads on SWE-Bench Pro and GDPval, 60.3 vs. 61.7 and 84.8 vs. 86.4. So Thom Wolf's "most" is accurate—not all. X user Michał Piszczek also pointed this out. X user Greg Glazewski focused on the DeepSWE gap and said he's waiting for third-party reruns.
Nanbeige's approach takes a detour: first make the teacher model solid, then distill smaller models. The 33B is the flagship teacher and will later train Nanbeige4.3-3B. The model card states it clearly: first raise the performance ceiling of small Agents.
The engineering details are also worth a look. The model supports a 524,288-token context, about 512K. In the chat template, enable_thinking is on by default; preserve_thinking is recommended on for multi-turn tool, office, and code Agent use, and off for regular chat Q&A. Passing tools enables the tool template; tool calls are recommended in XML format, with JSON also compatible. There are two sets of inference parameters: for Agent and tool tasks, temperature 1.0, top_p 0.95, max new tokens 65,536; for reasoning and chat, temperature 0.6, top_p 0.95, max new tokens 262,144. It can run on Transformers, SGLang, and vLLM.
512K sounds great, but it may not be great locally. X user Reza Harirchian did the math: with a dense Llama architecture, 52 layers, and 8 KV heads, the KV cache at fp16 is about 213KB per token. At the full 512K, the KV cache alone is about 110GB. Q4_K_M weights are about 21GB, so a 24GB GPU would have only about 10K context left. It's a good model—just don't treat 512K as a home setup.
Someone in the comments dropped a reaction meme:
Someone else brought out Qwen4 27B for a meme:
Some asked about quantization, some queued up for WikiBench, and some worried whether a lab model with no long-term track record might hide a backdoor. Ricardo Dias offered another angle: a recruiting site releasing a good model is itself a recruiting ad—the people who download the 33B are exactly the ML researchers it wants to hire.
The model card is here: Nanbeige4.3-33B, with the Base version at Nanbeige4.3-33B-Base. The original discussion comes from Thom Wolf and the Nanbeige announcement.
发布时间: 2026-10-26 20:33