AI Checks Itself: 5 Open-Source Repositories That Reduce Hallucinations and Errors
From Self-Refine to DeepEval, these 5 open-source projects let LLMs reflect on themselves and enable automated evaluation, removing manual proofreading and keeping AI output quality under control within the workflow.
Having AI check itself sounds like a tongue twister, but in practice it is a class of methods that is rapidly taking shape. In traditional workflows, LLM outputs are verified by humans afterward; these tools hand verification over to the model itself, using iterative feedback, self-reflection, and automated evaluation to reduce hallucinations and errors.
The Roundtable Show rounded up 5 open-source repositories on X, covering two approaches: self-correction and external evaluation. One commenter remarked after reading it that Reflexion has been sitting on their list for a long time and they still haven't tried it.
Self-Refine: Let the model repeatedly critique its own work
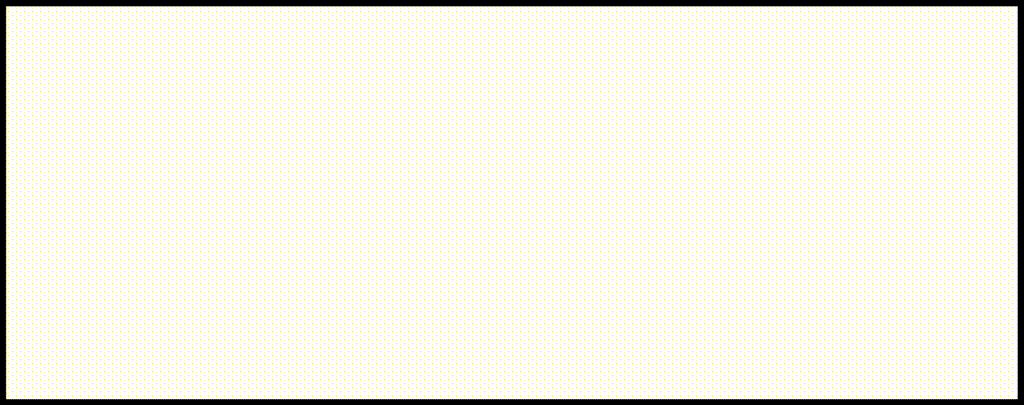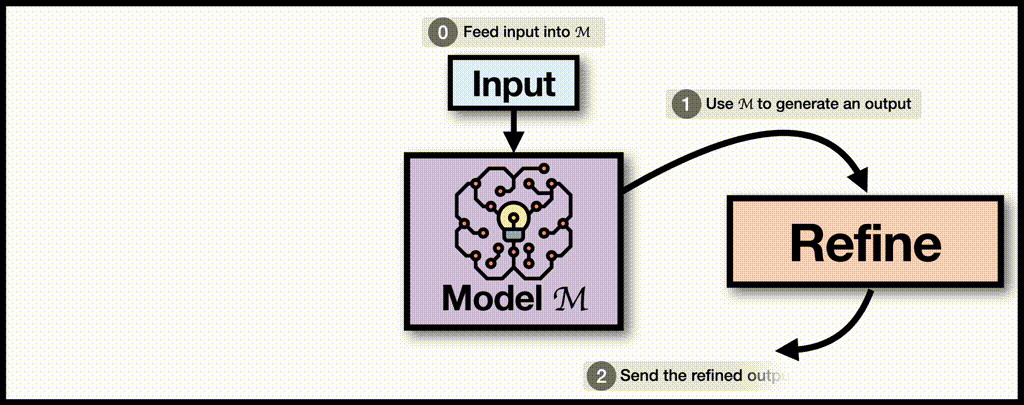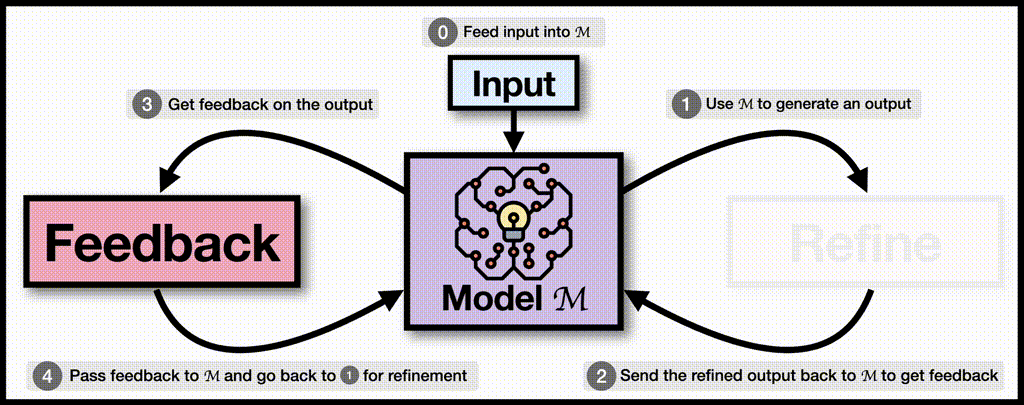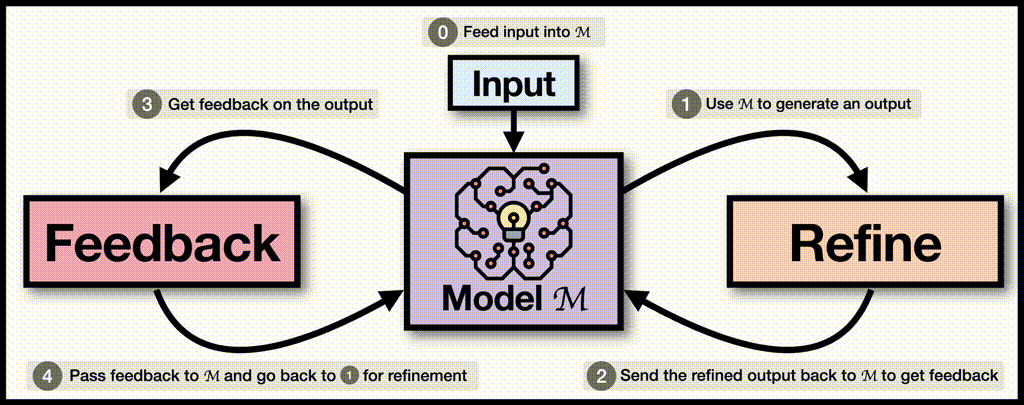
Self-Refine comes from a 2023 paper of the same name. The core workflow is simple: first generate a draft, then have the same model provide feedback on the draft, then improve it based on the feedback, and repeat. It requires no additional training and no larger model. It is suitable for tasks such as text generation and improving code readability. The project includes an animated demo that makes the iterative process easy to see.
Repository: https://github.com/madaan/self-refine
Reflexion: Using language for reinforcement learning
Reflexion is a NeurIPS 2023 paper. The idea is to have an agent write down reflections after a failure and store those reflections as text in memory, then review them before the next attempt. This is essentially replacing the value signal in reinforcement learning with natural-language feedback. The paper validated it on tasks such as HotPotQA, AlfWorld, and LeetcodeHardGym. This pattern is very useful for coding and reasoning scenarios.

Repository: https://github.com/noahshinn/reflexion
DeepEval: Test LLMs like Pytest
DeepEval is an open-source evaluation framework positioned similarly to Pytest, but for LLM applications. It includes built-in metrics such as G-Eval, hallucination detection, and answer relevance, and supports scenarios including RAG, AI agents, multi-turn conversations, and voice agents. It can run locally and can also be integrated into CI/CD. Official quick start: define test cases, set metrics, run deepeval test run, and you're done.

Repository: https://github.com/confident-ai/deepeval
The other two: Promptfoo and Inspect AI
Promptfoo focuses on regression testing for prompts (https://github.com/promptfoo/promptfoo). Inspect AI is maintained by the UK government's BEIS team and is used for evaluating model capabilities and safety (https://github.com/UKGovernmentBEIS/inspect_ai). Like the previous ones, they turn the question of whether AI output is actually reliable into an automatable process.
These five repositories approach the problem from different angles: some let the model reflect on itself, while others score it externally. What they have in common is that they no longer assume model output is correct by default; instead, they systematize the verification step. If you are debugging agents or RAG, each one is worth a look.
发布时间: 2026-10-27 03:56