When an Agent says "done," what do you use to verify it?
When you have an Agent modify its own Skill, the hardest part is never the modification—it's judging whether it got it right.
When an Agent Says "Done," What Do You Use to Verify It?
Dr. Xiaohui has recently been thinking about a question: how to make an AI Agent continuously improve itself. The deeper he researched, the more he realized he first had to answer another question: how do you know the Agent has actually done it right?
He recorded a video discussing three sets of practices: @poteto's Verification Skill, the Claude Code team's code review approach shared by @addyosamani, and @yetone's Agent Loop. He also talked about his own attempt to revamp an audio transcription workflow.
The video's conclusion isn't complicated. What really matters is writing the standards clearly, turning repeatable operations into tools, turning definite requirements into checks, and making sure every piece of feedback is retained.
It sounds like a correct but empty platitude. But that is exactly where most Skills get stuck.
The Current State of Most Skills
An operating manual relies on AI to understand and execute it. If it's well written, the AI can produce decent results. If it's vague, running the same task twice can produce two different outcomes.
What's more troublesome is that it's hard to tell which run was correct. When the Agent says "done," you can only choose to believe it or not.
Dr. Xiaohui provided a revamp guide. Have an Agent that can access the Skill files first read the existing files and make a diagnosis, then confirm the standards with the user, and only then start modifying. This order matters. One online commenter said that in the past they would rewrite entire sections right away, and didn't even realize when the acceptance criteria drifted.
The guide has four steps.
Step one: understand the existing Skill. Map out the workflow: look at task goals, steps, inputs and outputs, dependencies, and key branches. Which operations are already supported by tools? Which repetitive, deterministic steps are worth encapsulating as tools? How is task completion currently judged? Which requirements exist only as written descriptions without actual checks? After a user points out an error, how is it fixed? Will the same kind of problem recur? The principle is to preserve existing effective design as much as possible and not refactor for the sake of refactoring.
Step two: confirm acceptance criteria with the user. What does a good result look like? Which requirements must be met, and which are merely preferences? What errors are least acceptable? What problems have repeatedly occurred in the past? Which steps require human confirmation, and which can be safely left to the Agent to run automatically? Asking questions requires care: prioritize finding answers in documentation, historical feedback, and examples; ask only about missing or ambiguous points, and ask at most three questions per round.
Step three: implement the revamp. Structure it: create a concise workflow map. Tool it: encapsulate repetitive, deterministic operations into reusable tools, and when needed provide a unified CLI entry point, but don't force every Skill to develop a CLI. Make it verifiable: convert explicit requirements into automated checks, record what is checked, the results, and the evidence; when content changes, rerun the relevant verification; for subjective judgments such as semantics and aesthetics, keep human review. Make it improvable: establish feedback records, prioritize turning errors into approved examples, programmatic checks, or tool fixes, and update the Skill documentation only when necessary; distinguish one-off requirements from long-term rules to avoid unlimited rule growth.
Step four: test and deliver. Use existing examples for regression testing, compare before and after the revamp, and make sure important existing functionality has not regressed. Do not overwrite important original files without confirmation. Clearly distinguish four states: passed automated verification, passed AI evaluation, passed human confirmation, and not yet verified.
There is one core principle in the guide worth calling out separately: without evidence, do not claim verification has passed.
Online Commenters Added a Few Key Points
One commenter reminded that when letting an Agent directly edit a Skill, the real risk isn't a single bad edit. The trouble comes when wrong standards get written into the next iteration. At minimum, keep versioning, diff review, and one-click rollback.
Another commenter argued that execution and verification should be separated. The execution Agent is responsible for completing the task, independent tests are responsible for checking the results, and regression tests prevent old functionality from degrading. If the Agent executing the task is also responsible for modifying the Skill and judging its own success, it easily creates a closed-loop illusion: it thinks it has fixed things, when in reality it may just be making mistakes in a different way.
On the issue that checks themselves can proliferate, someone directly asked whether the guide includes a step for retiring old checks. Once many programmatic checks are written, over time there will be a pile of rules that no one dares to delete. This is a real problem. The guide emphasizes avoiding unlimited rule growth, but the retirement mechanism still depends on people cleaning up periodically.
The AI hands-on camp offered a concrete suggestion: before self-iteration, give the Skill a hard acceptance suite. For audio transcription, you can use word error rate plus key-entity recall as metrics, and keep three to five real tasks as a regression set. Without this yardstick, the Agent easily mistakes "ran successfully once" for "did it right," and the more it iterates, the further off course it goes.
Another commenter reminded that generalizing from feedback should avoid overfitting. A single error is worth fixing, but not every one-off request needs to become a permanent rule.
Speaking of audio transcription, one commenter asked what checks were added later. Another added: whether a transcription is right is exposed as soon as you search for proper nouns. That's a practical point. Things like names, numbers, and technical terms are either right or wrong.
Ambition Is Not Limited to One Dimension
Dr. Xiaohui's video cited an article by Felix Rieseberg that divides ambition into four categories: speed, height, depth, and breadth.
Speed is doing the same thing in less time. Height is abstracting up a level and focusing on the final result rather than a single task. Depth is treating the task like a top expert in the field would, digging down into the underlying data, tools, and problems. Breadth is bringing in multiple disciplines and using knowledge and methods you wouldn't normally touch.
This classification also applies to Skill revamps. Most Skills stay at the speed level, saving some typing time. Going up a level means asking what result this Skill is really supposed to produce. Going deeper means asking how the best people in the field would do this. Finally, it means bringing in different perspectives.
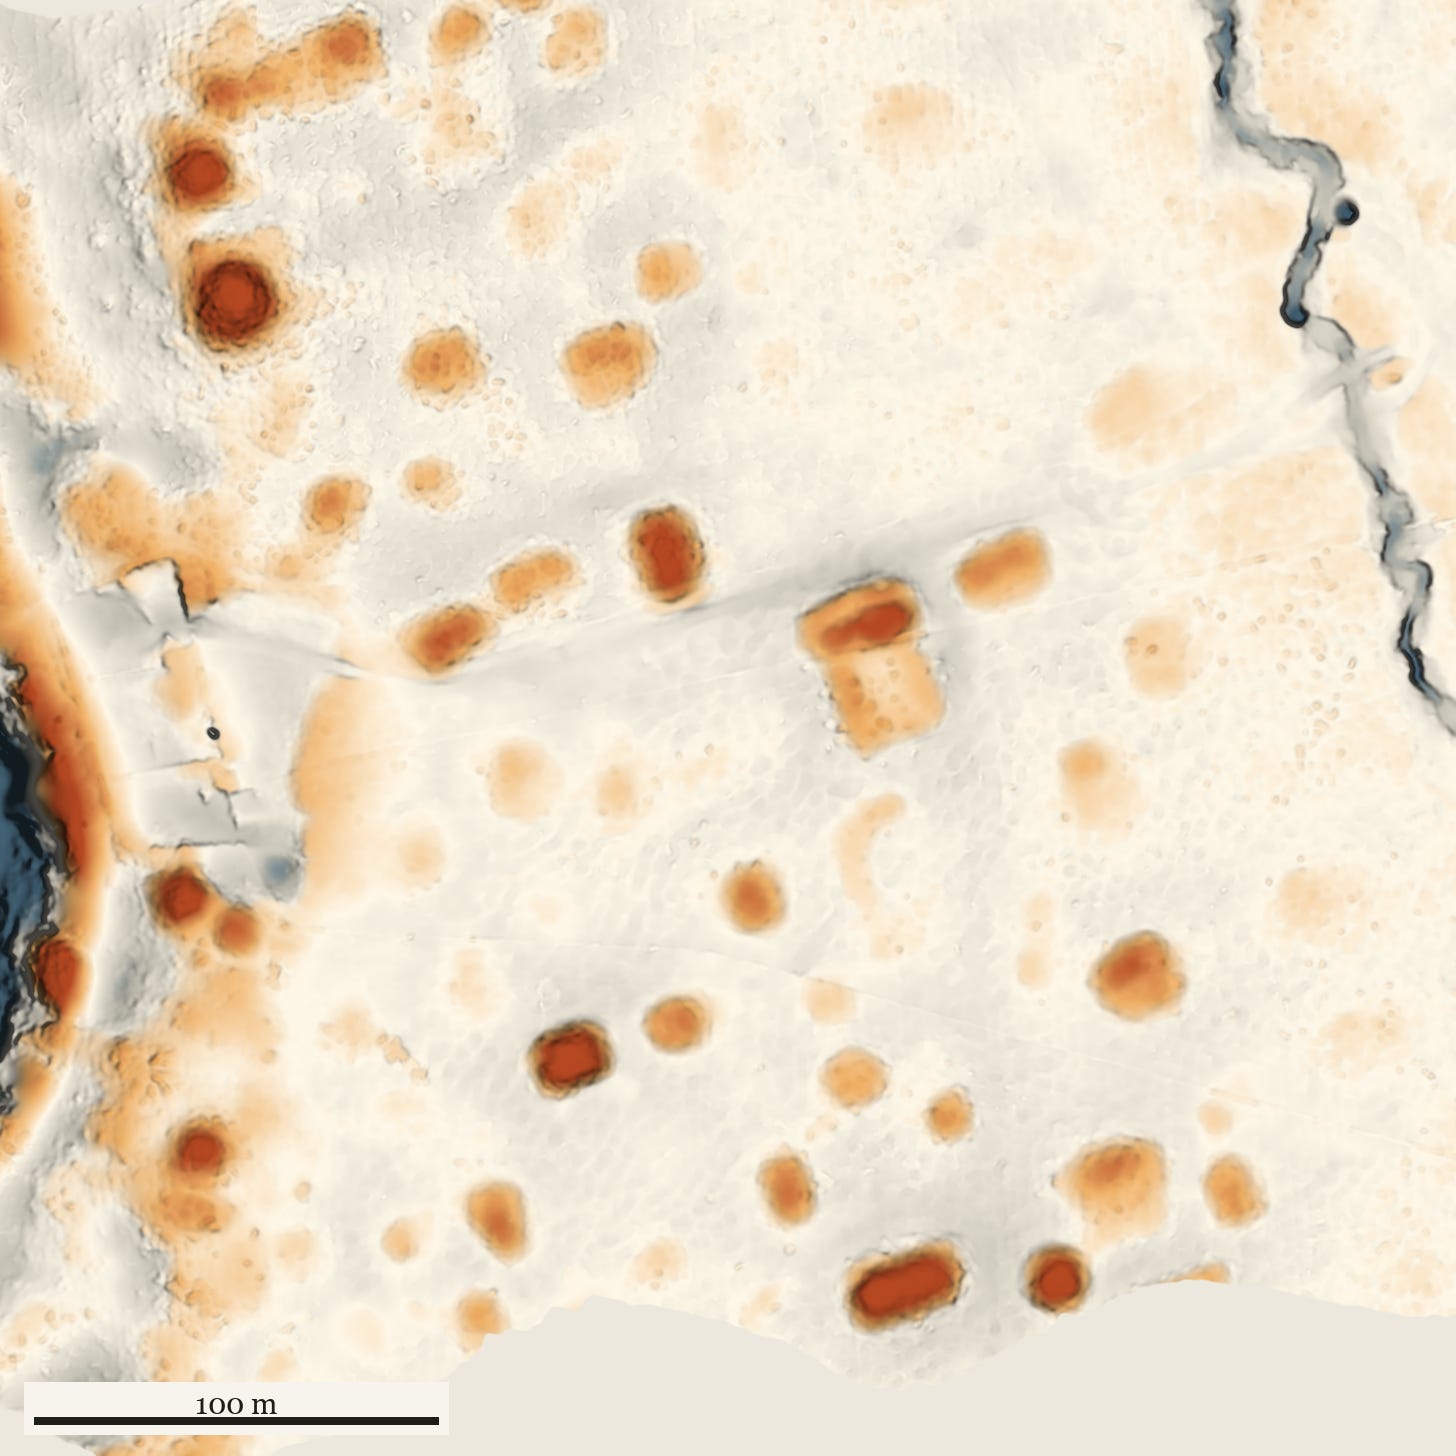
Nate's article about using Claude to find archaeological sites is a good example. He had Claude write a detector, first tested it on known sites, then used it to look for new places. After finding something, he had an independent AI "skeptic" try to overturn each discovery, and finally handed it to real archaeologists to judge. Throughout the whole process, verification wasn't the last step; it was every step.
Back to the question at the beginning. When an Agent says "done," what do you use to verify it?
The answer isn't complicated: first write down what counts as done.
发布时间: 2026-11-06 21:27