Routing in AI Workflows: a 124M Model Beats 9.4B by Not Generating Text
decision-cascade replaces routing, classification, and scoring in AI workflows—currently done by generating text and then parsing it—with typed probability outputs. A local 124M model reaches 0.873 on AG News with a p50 latency of 10ms. It is open source, but the default decision heads are randomly initialized, so to use it you still need to train your own or download weight bundles.
When adding routing, classification, and scoring to AI workflows, the default approach today is to have an LLM generate a passage of text and then extract the result with a regex or JSON parser. Every extra parsing layer adds fragility: change the model or tweak the prompt, and the parser may need to be rewritten.
decision-cascade takes another path: it does not generate text; it directly outputs typed decisions.
The input is a state string; it goes through an encoder to get features, which are then fed to several trained decision heads that output three kinds of results:
- Noul: a yes/no probability
- Choice: a distribution over the given options; the argmax is the choice
- Score: a weighted score and distribution over the given levels
Each result carries confidence and schema_version; clients validate it against the contract and do not need to parse natural language. The author, Dan Kornas, put it directly in the tweet: your agent needs a decision, not another generated paragraph.
The local-first cascade is its core design. Low-confidence questions are escalated to an external SystemOne-compatible model, and the rest are resolved locally. The two demos on GitHub make this mechanism quite intuitive.
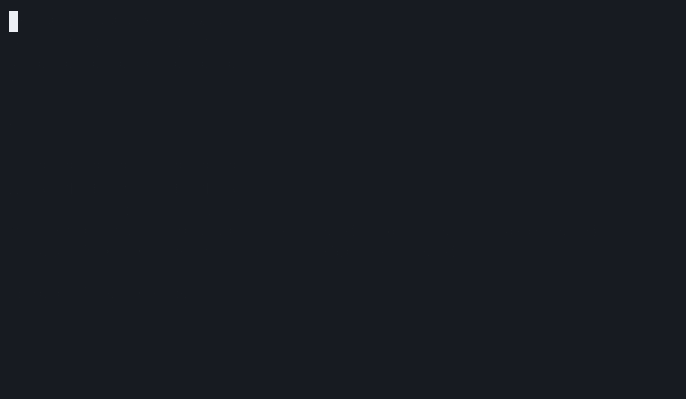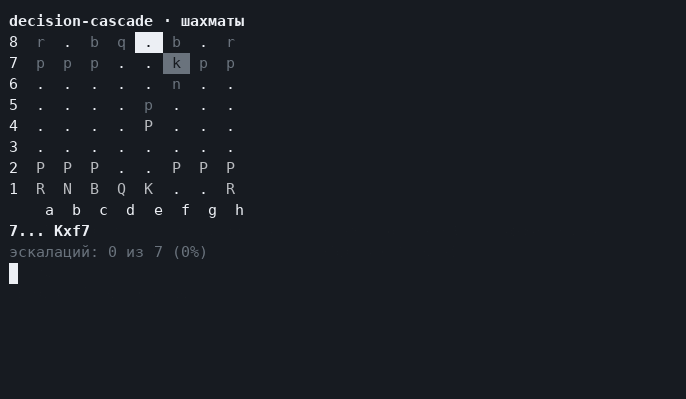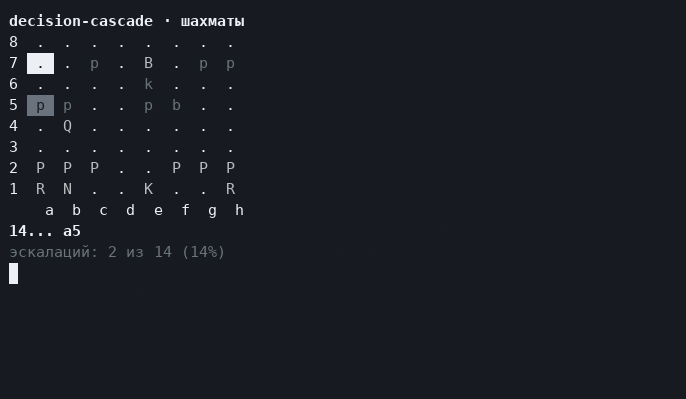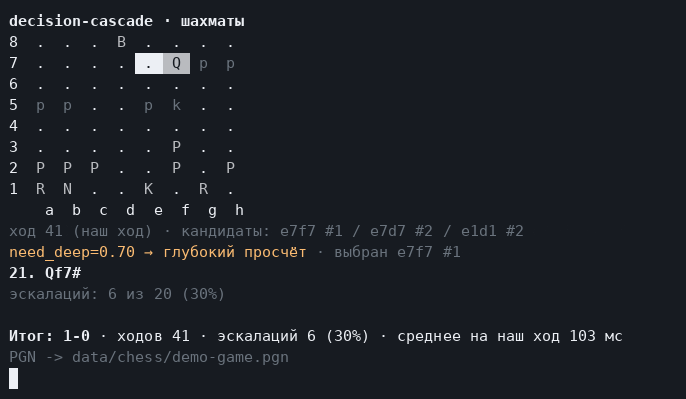
Chess against Stockfish: a 19% escalation rate closes half the gap to “always search deeply,” at 38% of the cost of full computation.
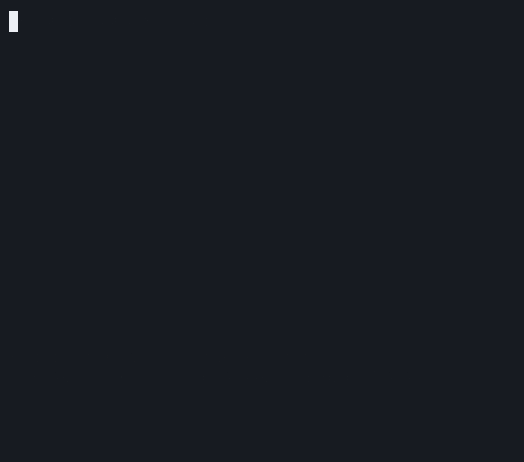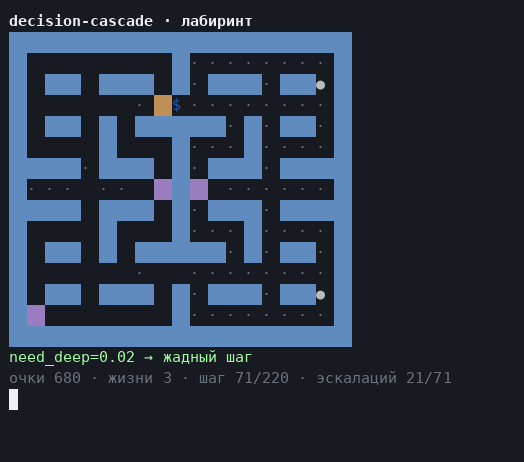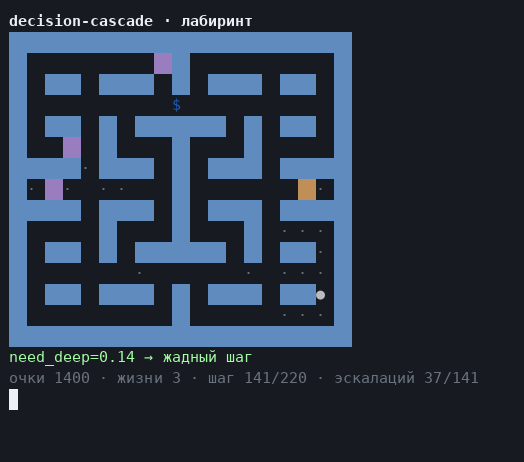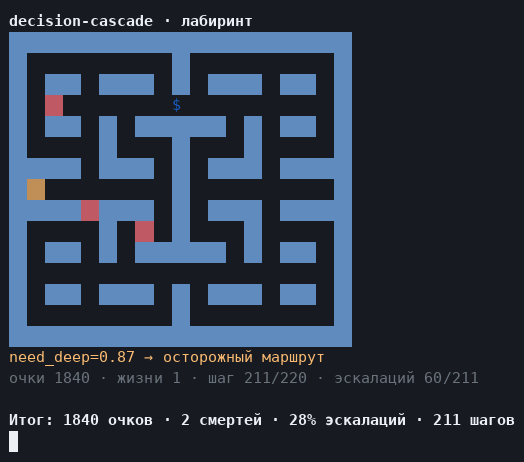
Maze game: the cautious strategy gets 94% of the score, with a 33% escalation rate—twice that of the greedy strategy.
The numbers on public datasets are worth a look. A 124M model (gpt2 + decision heads) versus 9.4B Clef-Flash and 421M Laya:
| Dataset | decision-cascade 124M | Clef-Flash 9.4B | Laya 421M |
|---|---|---|---|
| AG News accuracy | 0.873 | 0.855 | 0.662 |
| AG News p50 | 10ms | 130ms | 16ms |
| RouterBench accuracy | 0.542 | 0.442 | 0.312 |
| RouterBench p50 | 21ms | 170ms | 27ms |
The author himself added an honest caveat: RouterBench labels are counterfactual, and a trivial strategy like “always yes” already gets 0.775 accuracy, so what matters is the relative gap among participants, not absolute values.
On calibration, temperature scaling reduces ECE on AG News from 0.144 to 0.024 and on RouterBench from 0.547 to 0.024, with no change in accuracy. Without calibration, the heads’ confidence outputs are close to 1.0, and the cascade never triggers escalation.
One important caveat, which the author specifically mentions in the tweet: the default decision heads are randomly initialized. The repo says it even more clearly: after a clean clone, they are random heads; to make meaningful decisions, you have to train them yourself (SFT + RLCD) or download the weight bundles from the release. The v1.5.0 bundle includes support-gpt2 (0.926), public-gpt2 (0.880), and routerbench-gpt2 (0.548).
Quick start in two minutes:
pip install decision-cascade
python -m uvicorn api.server.main:app --port 8000
It starts with the hash encoder by default; no GPU is needed and no model download is required. Send a request:
{
  "state": "Stripe checkout has been failing for 3 days, we are losing revenue",
  "questions": {
    "urgent": {"type": "noul", "instructions": "Is the customer reporting urgency?"},
    "team": {"type": "choice", "instructions": "Which team should take it?",
             "options": ["billing", "integration", "sales", "support"]},
    "severity": {"type": "score", "instructions": "How upset is the customer?",
                 "levels": ["calm", "mild", "angry", "furious"]}
  }
}
It returns typed decisions with a trained: false flag, because the default heads are untrained. This flag is crucial, and the author does not hide it.
To get meaningful numbers, download the weight bundle:
gh release download v1.5.0 --pattern '*-weights.tar.gz' --repo slavabars/decision-cascade
Then start with the encoder and checkpoint directory specified.
The cascade has three strategies: threshold, risk budget, and benefit. The benefit strategy first asks “is it worth calling an external model?”; if the external model is worse than the local one on this problem, it does not escalate. There is also a conformal mode, which provides an upper bound guarantee on error rate, with more conservative coverage.
The risk-budget design deserves separate mention. confidence = 0.6 does not mean “60% correct”; it separately trains an estimator of P(error), and what you provide is “how much error rate is acceptable,” not an abstract threshold.
In the tweet replies, someone suggested a supplement: make “abstain” an output type as well. Give ambiguous inputs a path to human review instead of forcing them into the nearest label. This suggestion is very practical from an engineering perspective; the most expensive errors in classification systems often come from “being forced to pick one.”
Apache-2.0, runs locally, and data does not leave the machine. If your current workflow has a prompt segment specifically for classification followed by a parser, you can extract that segment and hand it to the decision layer. Note that it is not an out-of-the-box SaaS; the default heads are random weights, so to use it you first need labeled data or the weight bundle. The author says the same thing himself.
发布时间: 2026-11-17 07:26